CompStats.metrics
CompStats.metrics aims to facilitate performance measurement (with standard errors and confidence intervals) and statistical comparisons between algorithms on a single problem, wrapping the different scores and loss functions found on metrics.
To illustrate the use of CompStats.metrics, the following snippets show an example. The instructions load the necessary libraries, including the one to obtain the problem (e.g., digits), four different classifiers, and the last line is the score used to measure the performance and compare the algorithm.
>>> from sklearn.svm import LinearSVC
>>> from sklearn.naive_bayes import GaussianNB
>>> from sklearn.ensemble import RandomForestClassifier, HistGradientBoostingClassifier
>>> from sklearn.datasets import load_digits
>>> from sklearn.model_selection import train_test_split
>>> from CompStats.metrics import f1_score
The values printed in this page are illustrative: the train/validation split and the bootstrap samples are random, so the numbers differ from one execution to the next.
The first step is to load the digits problem and split the dataset into training and validation sets. The second step is to estimate the parameters of a linear Support Vector Machine and predict the validation set’s classes. The predictions are stored in the variable hy.
>>> X, y = load_digits(return_X_y=True)
>>> _ = train_test_split(X, y, test_size=0.3)
>>> X_train, X_val, y_train, y_val = _
>>> m = LinearSVC().fit(X_train, y_train)
>>> hy = m.predict(X_val)
Once the predictions are available, it is time to measure the algorithm’s performance, as seen in the following code. It is essential to note that the API used in metrics is followed; the difference is that the function returns an instance with different methods that can be used to estimate different performance statistics and compare algorithms.
>>> score = f1_score(y_val, hy, average='macro', name='Linear SVM')
>>> score
<Perf(func=f1_score, statistic=0.9521, se=0.0097)>
The previous code shows the macro-f1 score and, in parenthesis, its standard error. The actual performance value is stored in the attributes statistic and se
>>> score.statistic, score.se
(0.9521479775366307, 0.009717884979482313)
Continuing with the example, let us assume that one wants to test another classifier on the same problem, in this case, a random forest, as can be seen in the following two lines. The second line predicts the validation set and sets it to the analysis.
>>> ens = RandomForestClassifier().fit(X_train, y_train)
>>> score(ens.predict(X_val), name='Random Forest')
<Perf(func=f1_score)>
Statistic with its standard error (se)
statistic (se)
0.9720 (0.0076) <= Random Forest
0.9521 (0.0097) <= Linear SVM
Let us incorporate another predictions, now with Naive Bayes classifier, and Histogram Gradient Boosting as seen below.
>>> nb = GaussianNB().fit(X_train, y_train)
>>> score(nb.predict(X_val), name='Naive Bayes')
>>> hist = HistGradientBoostingClassifier().fit(X_train, y_train)
>>> score(hist.predict(X_val), name='Hist. Grad. Boost. Tree')
<Perf(func=f1_score)>
Statistic with its standard error (se)
statistic (se)
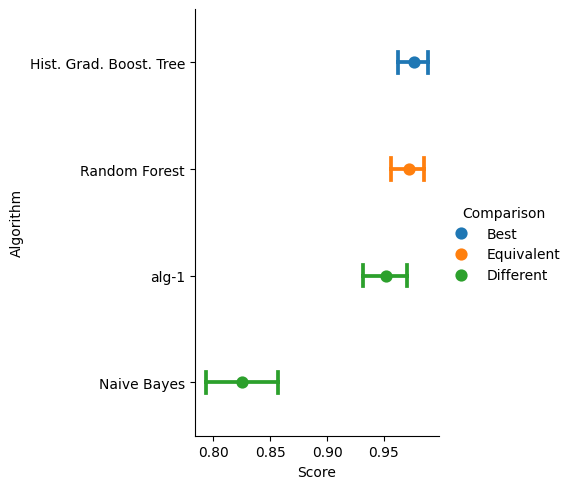
0.9759 (0.0068) <= Hist. Grad. Boost. Tree
0.9720 (0.0076) <= Random Forest
0.9521 (0.0097) <= Linear SVM
0.8266 (0.0159) <= Naive Bayes
The performance, its confidence interval (5%), and a statistical comparison (5%) between the best performing system with the rest of the algorithms is depicted in the following figure.
>>> score.plot()
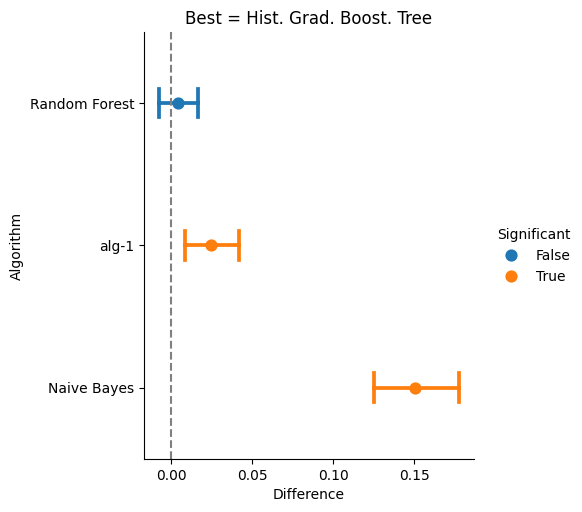
The final step is to compare the performance of the four classifiers, which can be done with the difference method, as seen next.
>>> diff = score.difference()
>>> diff
<Difference>
difference p-values  w.r.t Hist. Grad. Boost. Tree
0.0000 <= Naive Bayes
0.0100 <= Linear SVM
0.3240 <= Random Forest
The class Difference has the plot method that can be used to depict the difference with respect to the best.
>>> diff.plot()
Multi-measure Perf
A single competition can also be evaluated with more than one measure at once (e.g., macro-F1 together with macro-recall) by passing a list of functions to func. Score-type and error-type measures, with different Bigger-is-Better (BiB) directions, can even be combined this way into a single Perf instance, as long as each callable is tagged with its own BiB (or a matching list is passed to BiB). Every measure is evaluated on the same bootstrap resamples, so comparisons across algorithms remain paired for each measure.
Every CompStats.metrics wrapper exposes a .measure factory (e.g. f1_score.measure) that builds the tagged callable used internally as func; call it directly to compose several measures, as shown next.
>>> from CompStats.interface import Perf
>>> from CompStats.metrics import f1_score, recall_score
>>> mperf = Perf(y_val, hy, forest=ens.predict(X_val),
...              func=[f1_score.measure(average='macro'),
...                    recall_score.measure(average='macro')],
...              measure_names=['macro-F1', 'macro-Recall'])
>>> mperf
<Perf(func=macro-F1+macro-Recall)>
Statistic with its standard error (se)
statistic (se)
0.9783 (0.0061), 0.9786 (0.0060) <= forest
0.9440 (0.0098), 0.9442 (0.0098) <= Linear SVM
measure_names is optional; when omitted, each measure is labeled with its function’s __name__ (e.g. f1_score, recall_score). The properties statistic, se, and ci return one value per measure for every system.
>>> mperf.statistic
{'forest': array([0.97828319, 0.97855524]), 'alg-1': array([0.94399193, 0.94424915])}
>>> mperf.se
{'forest': array([0.00605715, 0.00595743]), 'alg-1': array([0.0098302 , 0.00978099])}
>>> mperf.ci
{'alg-1': (array([0.92393337, 0.92473771]), array([0.96193002, 0.96198806])), 'forest': (array([0.96618741, 0.9666813 ]), array([0.98902657, 0.98936809]))}
plot facets the resulting figure by measure, and difference reports one p-value per measure for each system compared to the best.
>>> mperf.plot()
>>> mperf.difference()
<Difference>
difference p-values
forest, forest <= Best
0.0000, 0.0000 <= alg-1
1.0000, 1.0000 <= forest
The convenience wrappers macro_f1, macro_recall, and macro_precision are ready-made, multi-measure-friendly shortcuts for macro-averaged F1, recall, and precision; each also exposes its own .measure factory (e.g. macro_f1.measure), so they can be combined the same way as any other CompStats.metrics wrapper.
>>> from CompStats.metrics import macro_f1, macro_recall
>>> Perf(y_val, hy, forest=ens.predict(X_val),
...      func=[macro_f1.measure(), macro_recall.measure()])
<Perf(func=f1_score+recall_score)>
Statistic with its standard error (se)
statistic (se)
0.9783 (0.0061), 0.9786 (0.0060) <= forest
0.9440 (0.0101), 0.9442 (0.0101) <= alg-1
- accuracy_score(y_true, *y_pred, normalize=True, sample_weight=None, num_samples: int = 500, n_jobs: int = -1, use_tqdm=True, **kwargs)[source]
Perfwithaccuracy_scoreas a score-type (bigger is better)func. The parameters not described can be found inaccuracy_score.- Parameters:
y_true (numpy.ndarray or pandas.DataFrame) – True measurement or could be a pandas.DataFrame where column label ‘y’ corresponds to the true measurement.
y_pred (numpy.ndarray) – Predictions, the algorithms will be identified with alg-k where k=1 is the first argument included in
y_pred.kwargs (numpy.ndarray) – Predictions, the algorithms will be identified using the keyword
num_samples (int) – Number of bootstrap samples, default=500.
n_jobs (int) – Number of jobs to compute the statistic, default=-1 corresponding to use all threads.
use_tqdm (bool) – Whether to use tqdm.tqdm to visualize the progress, default=True
accuracy_score.measurebuilds the tagged callable used internally asfunc; call it directly (e.g.accuracy_score.measure(...)) to combine this metric with others into a single, multi-measurePerf– seePerf’s class docstring for a worked example.accuracy_score
- balanced_accuracy_score(y_true, *y_pred, sample_weight=None, adjusted=False, num_samples: int = 500, n_jobs: int = -1, use_tqdm=True, **kwargs)[source]
Perfwithbalanced_accuracy_scoreas a score-type (bigger is better)func. The parameters not described can be found inbalanced_accuracy_score.- Parameters:
y_true (numpy.ndarray or pandas.DataFrame) – True measurement or could be a pandas.DataFrame where column label ‘y’ corresponds to the true measurement.
y_pred (numpy.ndarray) – Predictions, the algorithms will be identified with alg-k where k=1 is the first argument included in
y_pred.kwargs (numpy.ndarray) – Predictions, the algorithms will be identified using the keyword
num_samples (int) – Number of bootstrap samples, default=500.
n_jobs (int) – Number of jobs to compute the statistic, default=-1 corresponding to use all threads.
use_tqdm (bool) – Whether to use tqdm.tqdm to visualize the progress, default=True
balanced_accuracy_score.measurebuilds the tagged callable used internally asfunc; call it directly (e.g.balanced_accuracy_score.measure(...)) to combine this metric with others into a single, multi-measurePerf– seePerf’s class docstring for a worked example.balanced_accuracy_score
- top_k_accuracy_score(y_true, *y_score, k=2, normalize=True, sample_weight=None, labels=None, num_samples: int = 500, n_jobs: int = -1, use_tqdm=True, **kwargs)[source]
Perfwithtop_k_accuracy_scoreas a score-type (bigger is better)func. The parameters not described can be found intop_k_accuracy_score.- Parameters:
y_true (numpy.ndarray or pandas.DataFrame) – True measurement or could be a pandas.DataFrame where column label ‘y’ corresponds to the true measurement.
y_score (numpy.ndarray) – Predictions, the algorithms will be identified with alg-k where k=1 is the first argument included in
y_score.kwargs (numpy.ndarray) – Predictions, the algorithms will be identified using the keyword
num_samples (int) – Number of bootstrap samples, default=500.
n_jobs (int) – Number of jobs to compute the statistic, default=-1 corresponding to use all threads.
use_tqdm (bool) – Whether to use tqdm.tqdm to visualize the progress, default=True
top_k_accuracy_score.measurebuilds the tagged callable used internally asfunc; call it directly (e.g.top_k_accuracy_score.measure(...)) to combine this metric with others into a single, multi-measurePerf– seePerf’s class docstring for a worked example.top_k_accuracy_score
- average_precision_score(y_true, *y_score, average='macro', sample_weight=None, num_samples: int = 500, n_jobs: int = -1, use_tqdm=True, **kwargs)[source]
Perfwithaverage_precision_scoreas a score-type (bigger is better)func. The parameters not described can be found inaverage_precision_score.- Parameters:
y_true (numpy.ndarray or pandas.DataFrame) – True measurement or could be a pandas.DataFrame where column label ‘y’ corresponds to the true measurement.
y_score (numpy.ndarray) – Predictions, the algorithms will be identified with alg-k where k=1 is the first argument included in
y_score.kwargs (numpy.ndarray) – Predictions, the algorithms will be identified using the keyword
num_samples (int) – Number of bootstrap samples, default=500.
n_jobs (int) – Number of jobs to compute the statistic, default=-1 corresponding to use all threads.
use_tqdm (bool) – Whether to use tqdm.tqdm to visualize the progress, default=True
average_precision_score.measurebuilds the tagged callable used internally asfunc; call it directly (e.g.average_precision_score.measure(...)) to combine this metric with others into a single, multi-measurePerf– seePerf’s class docstring for a worked example.average_precision_score
- brier_score_loss(y_true, *y_proba, sample_weight=None, pos_label=None, num_samples: int = 500, n_jobs: int = -1, use_tqdm=True, **kwargs)[source]
Perfwithbrier_score_lossas a error-type (smaller is better)func. The parameters not described can be found inbrier_score_loss.- Parameters:
y_true (numpy.ndarray or pandas.DataFrame) – True measurement or could be a pandas.DataFrame where column label ‘y’ corresponds to the true measurement.
y_proba (numpy.ndarray) – Predictions, the algorithms will be identified with alg-k where k=1 is the first argument included in
y_proba.kwargs (numpy.ndarray) – Predictions, the algorithms will be identified using the keyword
num_samples (int) – Number of bootstrap samples, default=500.
n_jobs (int) – Number of jobs to compute the statistic, default=-1 corresponding to use all threads.
use_tqdm (bool) – Whether to use tqdm.tqdm to visualize the progress, default=True
brier_score_loss.measurebuilds the tagged callable used internally asfunc; call it directly (e.g.brier_score_loss.measure(...)) to combine this metric with others into a single, multi-measurePerf– seePerf’s class docstring for a worked example.brier_score_loss
- f1_score(y_true, *y_pred, labels=None, pos_label=1, average='binary', sample_weight=None, zero_division='warn', num_samples: int = 500, n_jobs: int = -1, use_tqdm=True, **kwargs)[source]
Perfwithf1_scoreas a score-type (bigger is better)func. The parameters not described can be found inf1_score.- Parameters:
y_true (numpy.ndarray or pandas.DataFrame) – True measurement or could be a pandas.DataFrame where column label ‘y’ corresponds to the true measurement.
y_pred (numpy.ndarray) – Predictions, the algorithms will be identified with alg-k where k=1 is the first argument included in
y_pred.kwargs (numpy.ndarray) – Predictions, the algorithms will be identified using the keyword
num_samples (int) – Number of bootstrap samples, default=500.
n_jobs (int) – Number of jobs to compute the statistic, default=-1 corresponding to use all threads.
use_tqdm (bool) – Whether to use tqdm.tqdm to visualize the progress, default=True
f1_score.measurebuilds the tagged callable used internally asfunc; call it directly (e.g.f1_score.measure(...)) to combine this metric with others into a single, multi-measurePerf– seePerf’s class docstring for a worked example.f1_score
- log_loss(y_true, *y_pred, normalize=True, sample_weight=None, labels=None, num_samples: int = 500, n_jobs: int = -1, use_tqdm=True, **kwargs)[source]
Perfwithlog_lossas a error-type (smaller is better)func. The parameters not described can be found inlog_loss.- Parameters:
y_true (numpy.ndarray or pandas.DataFrame) – True measurement or could be a pandas.DataFrame where column label ‘y’ corresponds to the true measurement.
y_pred (numpy.ndarray) – Predictions, the algorithms will be identified with alg-k where k=1 is the first argument included in
y_pred.kwargs (numpy.ndarray) – Predictions, the algorithms will be identified using the keyword
num_samples (int) – Number of bootstrap samples, default=500.
n_jobs (int) – Number of jobs to compute the statistic, default=-1 corresponding to use all threads.
use_tqdm (bool) – Whether to use tqdm.tqdm to visualize the progress, default=True
log_loss.measurebuilds the tagged callable used internally asfunc; call it directly (e.g.log_loss.measure(...)) to combine this metric with others into a single, multi-measurePerf– seePerf’s class docstring for a worked example.log_loss
- precision_score(y_true, *y_pred, labels=None, pos_label=1, average='binary', sample_weight=None, zero_division='warn', num_samples: int = 500, n_jobs: int = -1, use_tqdm=True, **kwargs)[source]
Perfwithprecision_scoreas a score-type (bigger is better)func. The parameters not described can be found inprecision_score.- Parameters:
y_true (numpy.ndarray or pandas.DataFrame) – True measurement or could be a pandas.DataFrame where column label ‘y’ corresponds to the true measurement.
y_pred (numpy.ndarray) – Predictions, the algorithms will be identified with alg-k where k=1 is the first argument included in
y_pred.kwargs (numpy.ndarray) – Predictions, the algorithms will be identified using the keyword
num_samples (int) – Number of bootstrap samples, default=500.
n_jobs (int) – Number of jobs to compute the statistic, default=-1 corresponding to use all threads.
use_tqdm (bool) – Whether to use tqdm.tqdm to visualize the progress, default=True
precision_score.measurebuilds the tagged callable used internally asfunc; call it directly (e.g.precision_score.measure(...)) to combine this metric with others into a single, multi-measurePerf– seePerf’s class docstring for a worked example.precision_score
- recall_score(y_true, *y_pred, labels=None, pos_label=1, average='binary', sample_weight=None, zero_division='warn', num_samples: int = 500, n_jobs: int = -1, use_tqdm=True, **kwargs)[source]
Perfwithrecall_scoreas a score-type (bigger is better)func. The parameters not described can be found inrecall_score.- Parameters:
y_true (numpy.ndarray or pandas.DataFrame) – True measurement or could be a pandas.DataFrame where column label ‘y’ corresponds to the true measurement.
y_pred (numpy.ndarray) – Predictions, the algorithms will be identified with alg-k where k=1 is the first argument included in
y_pred.kwargs (numpy.ndarray) – Predictions, the algorithms will be identified using the keyword
num_samples (int) – Number of bootstrap samples, default=500.
n_jobs (int) – Number of jobs to compute the statistic, default=-1 corresponding to use all threads.
use_tqdm (bool) – Whether to use tqdm.tqdm to visualize the progress, default=True
recall_score.measurebuilds the tagged callable used internally asfunc; call it directly (e.g.recall_score.measure(...)) to combine this metric with others into a single, multi-measurePerf– seePerf’s class docstring for a worked example.recall_score
- jaccard_score(y_true, *y_pred, labels=None, pos_label=1, average='binary', sample_weight=None, zero_division='warn', num_samples: int = 500, n_jobs: int = -1, use_tqdm=True, **kwargs)[source]
Perfwithjaccard_scoreas a score-type (bigger is better)func. The parameters not described can be found injaccard_score.- Parameters:
y_true (numpy.ndarray or pandas.DataFrame) – True measurement or could be a pandas.DataFrame where column label ‘y’ corresponds to the true measurement.
y_pred (numpy.ndarray) – Predictions, the algorithms will be identified with alg-k where k=1 is the first argument included in
y_pred.kwargs (numpy.ndarray) – Predictions, the algorithms will be identified using the keyword
num_samples (int) – Number of bootstrap samples, default=500.
n_jobs (int) – Number of jobs to compute the statistic, default=-1 corresponding to use all threads.
use_tqdm (bool) – Whether to use tqdm.tqdm to visualize the progress, default=True
jaccard_score.measurebuilds the tagged callable used internally asfunc; call it directly (e.g.jaccard_score.measure(...)) to combine this metric with others into a single, multi-measurePerf– seePerf’s class docstring for a worked example.jaccard_score
- roc_auc_score(y_true, *y_score, average='macro', sample_weight=None, max_fpr=None, multi_class='raise', labels=None, num_samples: int = 500, n_jobs: int = -1, use_tqdm=True, **kwargs)[source]
Perfwithroc_auc_scoreas a score-type (bigger is better)func. The parameters not described can be found inroc_auc_score.- Parameters:
y_true (numpy.ndarray or pandas.DataFrame) – True measurement or could be a pandas.DataFrame where column label ‘y’ corresponds to the true measurement.
y_score (numpy.ndarray) – Predictions, the algorithms will be identified with alg-k where k=1 is the first argument included in
y_score.kwargs (numpy.ndarray) – Predictions, the algorithms will be identified using the keyword
num_samples (int) – Number of bootstrap samples, default=500.
n_jobs (int) – Number of jobs to compute the statistic, default=-1 corresponding to use all threads.
use_tqdm (bool) – Whether to use tqdm.tqdm to visualize the progress, default=True
roc_auc_score.measurebuilds the tagged callable used internally asfunc; call it directly (e.g.roc_auc_score.measure(...)) to combine this metric with others into a single, multi-measurePerf– seePerf’s class docstring for a worked example.roc_auc_score
- d2_log_loss_score(y_true, *y_proba, sample_weight=None, labels=None, num_samples: int = 500, n_jobs: int = -1, use_tqdm=True, **kwargs)[source]
Perfwithd2_log_loss_scoreas a score-type (bigger is better)func. The parameters not described can be found ind2_log_loss_score.- Parameters:
y_true (numpy.ndarray or pandas.DataFrame) – True measurement or could be a pandas.DataFrame where column label ‘y’ corresponds to the true measurement.
y_proba (numpy.ndarray) – Predictions, the algorithms will be identified with alg-k where k=1 is the first argument included in
y_proba.kwargs (numpy.ndarray) – Predictions, the algorithms will be identified using the keyword
num_samples (int) – Number of bootstrap samples, default=500.
n_jobs (int) – Number of jobs to compute the statistic, default=-1 corresponding to use all threads.
use_tqdm (bool) – Whether to use tqdm.tqdm to visualize the progress, default=True
d2_log_loss_score.measurebuilds the tagged callable used internally asfunc; call it directly (e.g.d2_log_loss_score.measure(...)) to combine this metric with others into a single, multi-measurePerf– seePerf’s class docstring for a worked example.d2_log_loss_score
- macro_f1(y_true, *y_pred, labels=None, sample_weight=None, zero_division='warn', num_samples: int = 500, n_jobs: int = -1, use_tqdm=True, **kwargs)[source]
Perfwithf1_score(asfunc) with the parameteres needed to compute the macro score. The parameters not described can be found inf1_score- Parameters:
y_true (numpy.ndarray or pandas.DataFrame) – True measurement or could be a pandas.DataFrame where column label ‘y’ corresponds to the true measurement.
y_pred (numpy.ndarray) – Predictions, the algorithms will be identified with alg-k where k=1 is the first argument included in
y_pred.kwargs (numpy.ndarray) – Predictions, the algorithms will be identified using the keyword
num_samples (int) – Number of bootstrap samples, default=500.
n_jobs (int) – Number of jobs to compute the statistic, default=-1 corresponding to use all threads.
use_tqdm (bool) – Whether to use tqdm.tqdm to visualize the progress, default=True
- macro_recall(y_true, *y_pred, labels=None, sample_weight=None, zero_division='warn', num_samples: int = 500, n_jobs: int = -1, use_tqdm=True, **kwargs)[source]
Perfwithrecall_score(asfunc) with the parameteres needed to compute the macro score. The parameters not described can be found inrecall_score- Parameters:
y_true (numpy.ndarray or pandas.DataFrame) – True measurement or could be a pandas.DataFrame where column label ‘y’ corresponds to the true measurement.
y_pred (numpy.ndarray) – Predictions, the algorithms will be identified with alg-k where k=1 is the first argument included in
y_pred.kwargs (numpy.ndarray) – Predictions, the algorithms will be identified using the keyword
num_samples (int) – Number of bootstrap samples, default=500.
n_jobs (int) – Number of jobs to compute the statistic, default=-1 corresponding to use all threads.
use_tqdm (bool) – Whether to use tqdm.tqdm to visualize the progress, default=True
- macro_precision(y_true, *y_pred, labels=None, sample_weight=None, zero_division='warn', num_samples: int = 500, n_jobs: int = -1, use_tqdm=True, **kwargs)[source]
Perfwithprecision_score(asfunc) with the parameteres needed to compute the macro score. The parameters not described can be found inprecision_score- Parameters:
y_true (numpy.ndarray or pandas.DataFrame) – True measurement or could be a pandas.DataFrame where column label ‘y’ corresponds to the true measurement.
y_pred (numpy.ndarray) – Predictions, the algorithms will be identified with alg-k where k=1 is the first argument included in
y_pred.kwargs (numpy.ndarray) – Predictions, the algorithms will be identified using the keyword
num_samples (int) – Number of bootstrap samples, default=500.
n_jobs (int) – Number of jobs to compute the statistic, default=-1 corresponding to use all threads.
use_tqdm (bool) – Whether to use tqdm.tqdm to visualize the progress, default=True
- explained_variance_score(y_true, *y_pred, sample_weight=None, multioutput='uniform_average', force_finite=True, num_samples: int = 500, n_jobs: int = -1, use_tqdm=True, **kwargs)[source]
Perfwithexplained_variance_scoreas a score-type (bigger is better)func. The parameters not described can be found inexplained_variance_score.- Parameters:
y_true (numpy.ndarray or pandas.DataFrame) – True measurement or could be a pandas.DataFrame where column label ‘y’ corresponds to the true measurement.
y_pred (numpy.ndarray) – Predictions, the algorithms will be identified with alg-k where k=1 is the first argument included in
y_pred.kwargs (numpy.ndarray) – Predictions, the algorithms will be identified using the keyword
num_samples (int) – Number of bootstrap samples, default=500.
n_jobs (int) – Number of jobs to compute the statistic, default=-1 corresponding to use all threads.
use_tqdm (bool) – Whether to use tqdm.tqdm to visualize the progress, default=True
explained_variance_score.measurebuilds the tagged callable used internally asfunc; call it directly (e.g.explained_variance_score.measure(...)) to combine this metric with others into a single, multi-measurePerf– seePerf’s class docstring for a worked example.explained_variance_score
- max_error(y_true, *y_pred, num_samples: int = 500, n_jobs: int = -1, use_tqdm=True, **kwargs)[source]
Perfwithmax_erroras a error-type (smaller is better)func. The parameters not described can be found inmax_error.- Parameters:
y_true (numpy.ndarray or pandas.DataFrame) – True measurement or could be a pandas.DataFrame where column label ‘y’ corresponds to the true measurement.
y_pred (numpy.ndarray) – Predictions, the algorithms will be identified with alg-k where k=1 is the first argument included in
y_pred.kwargs (numpy.ndarray) – Predictions, the algorithms will be identified using the keyword
num_samples (int) – Number of bootstrap samples, default=500.
n_jobs (int) – Number of jobs to compute the statistic, default=-1 corresponding to use all threads.
use_tqdm (bool) – Whether to use tqdm.tqdm to visualize the progress, default=True
max_error.measurebuilds the tagged callable used internally asfunc; call it directly (e.g.max_error.measure(...)) to combine this metric with others into a single, multi-measurePerf– seePerf’s class docstring for a worked example.max_error
- mean_absolute_error(y_true, *y_pred, sample_weight=None, multioutput='uniform_average', num_samples: int = 500, n_jobs: int = -1, use_tqdm=True, **kwargs)[source]
Perfwithmean_absolute_erroras a error-type (smaller is better)func. The parameters not described can be found inmean_absolute_error.- Parameters:
y_true (numpy.ndarray or pandas.DataFrame) – True measurement or could be a pandas.DataFrame where column label ‘y’ corresponds to the true measurement.
y_pred (numpy.ndarray) – Predictions, the algorithms will be identified with alg-k where k=1 is the first argument included in
y_pred.kwargs (numpy.ndarray) – Predictions, the algorithms will be identified using the keyword
num_samples (int) – Number of bootstrap samples, default=500.
n_jobs (int) – Number of jobs to compute the statistic, default=-1 corresponding to use all threads.
use_tqdm (bool) – Whether to use tqdm.tqdm to visualize the progress, default=True
mean_absolute_error.measurebuilds the tagged callable used internally asfunc; call it directly (e.g.mean_absolute_error.measure(...)) to combine this metric with others into a single, multi-measurePerf– seePerf’s class docstring for a worked example.mean_absolute_error
- mean_squared_error(y_true, *y_pred, sample_weight=None, multioutput='uniform_average', num_samples: int = 500, n_jobs: int = -1, use_tqdm=True, **kwargs)[source]
Perfwithmean_squared_erroras a error-type (smaller is better)func. The parameters not described can be found inmean_squared_error.- Parameters:
y_true (numpy.ndarray or pandas.DataFrame) – True measurement or could be a pandas.DataFrame where column label ‘y’ corresponds to the true measurement.
y_pred (numpy.ndarray) – Predictions, the algorithms will be identified with alg-k where k=1 is the first argument included in
y_pred.kwargs (numpy.ndarray) – Predictions, the algorithms will be identified using the keyword
num_samples (int) – Number of bootstrap samples, default=500.
n_jobs (int) – Number of jobs to compute the statistic, default=-1 corresponding to use all threads.
use_tqdm (bool) – Whether to use tqdm.tqdm to visualize the progress, default=True
mean_squared_error.measurebuilds the tagged callable used internally asfunc; call it directly (e.g.mean_squared_error.measure(...)) to combine this metric with others into a single, multi-measurePerf– seePerf’s class docstring for a worked example.mean_squared_error
- root_mean_squared_error(y_true, *y_pred, sample_weight=None, multioutput='uniform_average', num_samples: int = 500, n_jobs: int = -1, use_tqdm=True, **kwargs)[source]
Perfwithroot_mean_squared_erroras a error-type (smaller is better)func. The parameters not described can be found inroot_mean_squared_error.- Parameters:
y_true (numpy.ndarray or pandas.DataFrame) – True measurement or could be a pandas.DataFrame where column label ‘y’ corresponds to the true measurement.
y_pred (numpy.ndarray) – Predictions, the algorithms will be identified with alg-k where k=1 is the first argument included in
y_pred.kwargs (numpy.ndarray) – Predictions, the algorithms will be identified using the keyword
num_samples (int) – Number of bootstrap samples, default=500.
n_jobs (int) – Number of jobs to compute the statistic, default=-1 corresponding to use all threads.
use_tqdm (bool) – Whether to use tqdm.tqdm to visualize the progress, default=True
root_mean_squared_error.measurebuilds the tagged callable used internally asfunc; call it directly (e.g.root_mean_squared_error.measure(...)) to combine this metric with others into a single, multi-measurePerf– seePerf’s class docstring for a worked example.root_mean_squared_error
- mean_squared_log_error(y_true, *y_pred, sample_weight=None, multioutput='uniform_average', num_samples: int = 500, n_jobs: int = -1, use_tqdm=True, **kwargs)[source]
Perfwithmean_squared_log_erroras a error-type (smaller is better)func. The parameters not described can be found inmean_squared_log_error.- Parameters:
y_true (numpy.ndarray or pandas.DataFrame) – True measurement or could be a pandas.DataFrame where column label ‘y’ corresponds to the true measurement.
y_pred (numpy.ndarray) – Predictions, the algorithms will be identified with alg-k where k=1 is the first argument included in
y_pred.kwargs (numpy.ndarray) – Predictions, the algorithms will be identified using the keyword
num_samples (int) – Number of bootstrap samples, default=500.
n_jobs (int) – Number of jobs to compute the statistic, default=-1 corresponding to use all threads.
use_tqdm (bool) – Whether to use tqdm.tqdm to visualize the progress, default=True
mean_squared_log_error.measurebuilds the tagged callable used internally asfunc; call it directly (e.g.mean_squared_log_error.measure(...)) to combine this metric with others into a single, multi-measurePerf– seePerf’s class docstring for a worked example.mean_squared_log_error
- root_mean_squared_log_error(y_true, *y_pred, sample_weight=None, multioutput='uniform_average', num_samples: int = 500, n_jobs: int = -1, use_tqdm=True, **kwargs)[source]
Perfwithroot_mean_squared_log_erroras a error-type (smaller is better)func. The parameters not described can be found inroot_mean_squared_log_error.- Parameters:
y_true (numpy.ndarray or pandas.DataFrame) – True measurement or could be a pandas.DataFrame where column label ‘y’ corresponds to the true measurement.
y_pred (numpy.ndarray) – Predictions, the algorithms will be identified with alg-k where k=1 is the first argument included in
y_pred.kwargs (numpy.ndarray) – Predictions, the algorithms will be identified using the keyword
num_samples (int) – Number of bootstrap samples, default=500.
n_jobs (int) – Number of jobs to compute the statistic, default=-1 corresponding to use all threads.
use_tqdm (bool) – Whether to use tqdm.tqdm to visualize the progress, default=True
root_mean_squared_log_error.measurebuilds the tagged callable used internally asfunc; call it directly (e.g.root_mean_squared_log_error.measure(...)) to combine this metric with others into a single, multi-measurePerf– seePerf’s class docstring for a worked example.root_mean_squared_log_error
- median_absolute_error(y_true, *y_pred, sample_weight=None, multioutput='uniform_average', num_samples: int = 500, n_jobs: int = -1, use_tqdm=True, **kwargs)[source]
Perfwithmedian_absolute_erroras a error-type (smaller is better)func. The parameters not described can be found inmedian_absolute_error.- Parameters:
y_true (numpy.ndarray or pandas.DataFrame) – True measurement or could be a pandas.DataFrame where column label ‘y’ corresponds to the true measurement.
y_pred (numpy.ndarray) – Predictions, the algorithms will be identified with alg-k where k=1 is the first argument included in
y_pred.kwargs (numpy.ndarray) – Predictions, the algorithms will be identified using the keyword
num_samples (int) – Number of bootstrap samples, default=500.
n_jobs (int) – Number of jobs to compute the statistic, default=-1 corresponding to use all threads.
use_tqdm (bool) – Whether to use tqdm.tqdm to visualize the progress, default=True
median_absolute_error.measurebuilds the tagged callable used internally asfunc; call it directly (e.g.median_absolute_error.measure(...)) to combine this metric with others into a single, multi-measurePerf– seePerf’s class docstring for a worked example.median_absolute_error
- r2_score(y_true, *y_pred, sample_weight=None, multioutput='uniform_average', force_finite=True, num_samples: int = 500, n_jobs: int = -1, use_tqdm=True, **kwargs)[source]
Perfwithr2_scoreas a score-type (bigger is better)func. The parameters not described can be found inr2_score.- Parameters:
y_true (numpy.ndarray or pandas.DataFrame) – True measurement or could be a pandas.DataFrame where column label ‘y’ corresponds to the true measurement.
y_pred (numpy.ndarray) – Predictions, the algorithms will be identified with alg-k where k=1 is the first argument included in
y_pred.kwargs (numpy.ndarray) – Predictions, the algorithms will be identified using the keyword
num_samples (int) – Number of bootstrap samples, default=500.
n_jobs (int) – Number of jobs to compute the statistic, default=-1 corresponding to use all threads.
use_tqdm (bool) – Whether to use tqdm.tqdm to visualize the progress, default=True
r2_score.measurebuilds the tagged callable used internally asfunc; call it directly (e.g.r2_score.measure(...)) to combine this metric with others into a single, multi-measurePerf– seePerf’s class docstring for a worked example.r2_score
- mean_poisson_deviance(y_true, *y_pred, sample_weight=None, num_samples: int = 500, n_jobs: int = -1, use_tqdm=True, **kwargs)[source]
Perfwithmean_poisson_devianceas a error-type (smaller is better)func. The parameters not described can be found inmean_poisson_deviance.- Parameters:
y_true (numpy.ndarray or pandas.DataFrame) – True measurement or could be a pandas.DataFrame where column label ‘y’ corresponds to the true measurement.
y_pred (numpy.ndarray) – Predictions, the algorithms will be identified with alg-k where k=1 is the first argument included in
y_pred.kwargs (numpy.ndarray) – Predictions, the algorithms will be identified using the keyword
num_samples (int) – Number of bootstrap samples, default=500.
n_jobs (int) – Number of jobs to compute the statistic, default=-1 corresponding to use all threads.
use_tqdm (bool) – Whether to use tqdm.tqdm to visualize the progress, default=True
mean_poisson_deviance.measurebuilds the tagged callable used internally asfunc; call it directly (e.g.mean_poisson_deviance.measure(...)) to combine this metric with others into a single, multi-measurePerf– seePerf’s class docstring for a worked example.mean_poisson_deviance
- mean_gamma_deviance(y_true, *y_pred, sample_weight=None, num_samples: int = 500, n_jobs: int = -1, use_tqdm=True, **kwargs)[source]
Perfwithmean_gamma_devianceas a error-type (smaller is better)func. The parameters not described can be found inmean_gamma_deviance.- Parameters:
y_true (numpy.ndarray or pandas.DataFrame) – True measurement or could be a pandas.DataFrame where column label ‘y’ corresponds to the true measurement.
y_pred (numpy.ndarray) – Predictions, the algorithms will be identified with alg-k where k=1 is the first argument included in
y_pred.kwargs (numpy.ndarray) – Predictions, the algorithms will be identified using the keyword
num_samples (int) – Number of bootstrap samples, default=500.
n_jobs (int) – Number of jobs to compute the statistic, default=-1 corresponding to use all threads.
use_tqdm (bool) – Whether to use tqdm.tqdm to visualize the progress, default=True
mean_gamma_deviance.measurebuilds the tagged callable used internally asfunc; call it directly (e.g.mean_gamma_deviance.measure(...)) to combine this metric with others into a single, multi-measurePerf– seePerf’s class docstring for a worked example.mean_gamma_deviance
- mean_absolute_percentage_error(y_true, *y_pred, sample_weight=None, multioutput='uniform_average', num_samples: int = 500, n_jobs: int = -1, use_tqdm=True, **kwargs)[source]
Perfwithmean_absolute_percentage_erroras a error-type (smaller is better)func. The parameters not described can be found inmean_absolute_percentage_error.- Parameters:
y_true (numpy.ndarray or pandas.DataFrame) – True measurement or could be a pandas.DataFrame where column label ‘y’ corresponds to the true measurement.
y_pred (numpy.ndarray) – Predictions, the algorithms will be identified with alg-k where k=1 is the first argument included in
y_pred.kwargs (numpy.ndarray) – Predictions, the algorithms will be identified using the keyword
num_samples (int) – Number of bootstrap samples, default=500.
n_jobs (int) – Number of jobs to compute the statistic, default=-1 corresponding to use all threads.
use_tqdm (bool) – Whether to use tqdm.tqdm to visualize the progress, default=True
mean_absolute_percentage_error.measurebuilds the tagged callable used internally asfunc; call it directly (e.g.mean_absolute_percentage_error.measure(...)) to combine this metric with others into a single, multi-measurePerf– seePerf’s class docstring for a worked example.mean_absolute_percentage_error
- pearsonr(y_true, *y_pred, alternative='two-sided', method=None, num_samples: int = 500, n_jobs: int = -1, use_tqdm=True, **kwargs)[source]
-
- Parameters:
y_true (numpy.ndarray or pandas.DataFrame) – True measurement or could be a pandas.DataFrame where column label ‘y’ corresponds to the true measurement.
y_pred (numpy.ndarray) – Predictions, the algorithms will be identified with alg-k where k=1 is the first argument included in
y_pred.kwargs (numpy.ndarray) – Predictions, the algorithms will be identified using the keyword
num_samples (int) – Number of bootstrap samples, default=500.
n_jobs (int) – Number of jobs to compute the statistic, default=-1 corresponding to use all threads.
use_tqdm (bool) – Whether to use tqdm.tqdm to visualize the progress, default=True